There are three approaches to making your website content available as clean markdown for AI systems. Two of them have a fatal flaw. The third is how Getmd works.
Understanding the difference matters because the approach you choose determines whether AI systems are reading your current content or something you published weeks or months ago and forgot to update.
Approach 1: Static file export
The simplest approach. You convert your web pages to markdown files, upload them to your server, and point AI crawlers to them. It works. It’s free. And for a website that rarely changes, it’s genuinely fine.
The problem arrives the moment your website is active. You update your pricing page – but the markdown file still shows last quarter’s prices. You publish a new case study – but it doesn’t exist as a markdown file yet. You rewrite your homepage positioning – but the markdown version still describes your old value proposition.
Static exports go stale immediately. And unlike your live website, which has a CMS and a publishing workflow, static markdown files have no natural mechanism to stay in sync. They rely entirely on someone remembering to regenerate and re-upload them every time anything changes.
For a website with 10 pages that changes once a month, this is manageable. For a business with 50, 100, or 500 pages publishing regularly, it’s a maintenance disaster. The files drift out of sync within days, and nobody notices until an AI system cites your old pricing in someone’s answer.
Approach 2: Scheduled batch generation
A step up from static exports. A script runs on a schedule – daily, weekly – and regenerates all your markdown files from your live website. Better than manual exports because at least there’s automation. But the staleness problem is still there, just reduced.
If your batch runs daily at midnight, any change made at 9am won’t be reflected until the next night. For content that moves fast – pricing updates, product launches, inventory changes, breaking news – a 24-hour delay means AI systems are serving outdated information for most of the day.
And batch jobs have their own operational challenges. They need hosting, monitoring, error handling, and someone to notice when they silently fail. A broken cron job that stops running is invisible until someone checks – and in the meantime, your markdown files are getting older by the day.
Approach 3: Live conversion with intelligent caching
This is how Getmd works.
When an AI crawler requests a page through your Getmd subdomain, the system fetches the current HTML from your live website, converts it to clean markdown in real time, and serves it to the crawler. The converted markdown is then cached so subsequent requests are served instantly without hitting your origin server again.
The cache has a configurable time-to-live (TTL). You set how long cached content is considered fresh. When the TTL expires, the next request triggers a fresh conversion from your live site.
The range goes from 24 hours (for stable, rarely-updated content) down to every five minutes (for fast-moving content where freshness is critical).
Why live conversion matters
The difference between approaches isn’t just operational convenience – it affects your AI visibility directly.
AI systems trust fresh content. When AI crawlers encounter content with current dates, current pricing, current team members, and current product descriptions, that content is more likely to be selected as a source. Stale content – especially content that contradicts information on the live website – signals unreliability.
Your llms.txt promises are only as good as your pages. Your llms.txt tells AI systems “here are our most important pages.” When an AI crawler follows those links and finds markdown that matches the live website, trust is maintained. When it finds a version from three months ago with different information, the disconnect undermines the entire discovery layer.
Content freshness is a competitive signal. If two sources answer the same question and one was last updated yesterday while the other was last updated six months ago, the AI system has a reason to prefer the fresher source. This isn’t theoretical – AI systems track content freshness as part of their source evaluation.
What “every five minutes” actually means
Let’s be specific about how Getmd’s caching works, because this is the part people usually have questions about.
The first request. When an AI crawler requests a page that isn’t in the cache (or whose cache has expired), Getmd fetches the page from your live website, converts it to markdown, serves it to the crawler, and stores the result in the cache. This takes slightly longer than a cached response – typically under two seconds.
Subsequent requests. Every request after that is served directly from the cache. Sub-100ms response times. Your origin server isn’t touched. The AI crawler gets clean markdown instantly.
Cache expiry. When the TTL you’ve set expires, the cached version is marked stale. The next request triggers a fresh conversion. If no request comes in, nothing happens – there’s no unnecessary fetching of pages nobody is requesting.
The five-minute option. Setting a five-minute TTL means that at most, an AI crawler will see content that’s five minutes old. For most websites, this is essentially real-time. Even for fast-moving content like pricing or inventory, a five-minute window is more than sufficient.
The practical default. Most Getmd customers run with a one-hour TTL. It’s a good balance between freshness and efficiency. Pages that change frequently (pricing, product pages) might get a shorter TTL. Pages that rarely change (about pages, evergreen guides) might get a longer one.
What this means for your origin server
A common concern: “If AI crawlers are requesting my pages frequently, won’t that overwhelm my server?”
No – and this is one of the key benefits of the caching layer.
Getmd’s cache sits between AI crawlers and your website. When ClaudeBot, GPTBot, PerplexityBot, and a dozen other crawlers all request the same page within an hour, your server handles one request. The cache serves the rest.
Without Getmd (or something like it), each of those crawlers hits your origin server directly. That’s 12+ separate requests for the same page, each one requiring your server to render the full HTML. With Getmd, your server renders once. The cache handles the rest.
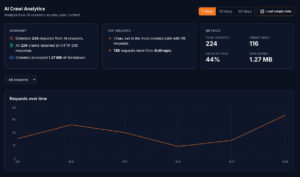
For sites that receive heavy AI crawler traffic – and as we document in our analytics guides, some sites receive thousands of AI crawler requests per day – this caching layer significantly reduces origin server load.
Why not just use a CDN?
Fair question. CDNs like Cloudflare, Fastly, and CloudFront already cache content. Why not just serve cached HTML?
Because the format problem doesn’t go away with caching. A CDN caches your HTML faster – it doesn’t make it cleaner. The AI crawler still receives 16,000 tokens of bloated HTML instead of 3,000 tokens of clean markdown. The cache is fast, but the content is still noisy.
Getmd’s conversion layer is the critical difference. It’s not just caching – it’s caching after conversion. The content your CDN serves to human browsers remains untouched. The content Getmd serves to AI crawlers is the same information, but in the format they prefer to consume.
Static vs live: a practical comparison
| Dimension | Static export | Scheduled batch | Getmd (live + cache) |
|---|---|---|---|
| Freshness | Manual updates only | Batch schedule (daily/weekly) | Configurable TTL (5 min – 24 hrs) |
| Maintenance | High – manual per page | Medium – script monitoring | None – fully automated |
| Sync risk | Pages drift immediately | Pages drift between batches | Always in sync within TTL |
| Scale | Breaks at 50+ pages | Works but slow at scale | Handles any site size |
| Origin server load | No impact (static files) | Batch load during generation | Minimal – cache absorbs traffic |
| Cost | Free (your time aside) | Hosting + monitoring | Getmd subscription |
For sites with fewer than 10 pages that change quarterly, static exports are fine. For anything beyond that, the freshness and maintenance advantages of live conversion with caching become significant.
How to think about your TTL
When configuring your Getmd cache TTL, consider the type of content on each page:
5–15 minutes: Pricing pages, product availability, inventory, news, anything with time-sensitive information that would mislead an AI system if stale.
1 hour (the default): Most service pages, blog posts, about pages, team pages, case studies. Content that changes occasionally but not minute-to-minute.
6–24 hours: Evergreen guides, documentation, foundational content that changes rarely. The cache saves compute without risking staleness.
You don’t have to set a single TTL for your entire site. Getmd lets you think about freshness on a per-content-type basis, matching the cache to how your content actually behaves.
The bottom line
The choice between static, scheduled, and live conversion comes down to a question: how important is it that AI systems read your current content?
If you’re comfortable with AI systems potentially citing last month’s pricing, last quarter’s team page, or a product description you’ve since rewritten, static exports are fine.
If you want AI systems to see what your human visitors see – current, accurate, up-to-date – you need live conversion with intelligent caching. That’s what Getmd provides.
Keep your AI-readable content as fresh as your website. Start your free trial →
This is part of our series on making your website visible to AI. Also in this series:
- Introducing Getmd: Make Your Website Visible to AI
- What is Markdown and Why Every AI System Prefers It
- What is llms.txt? The Discovery File AI Crawlers Actually Read
- llms.txt vs llms-full.txt: What the Data Actually Shows
- The Clean Markdown Problem: Why Most Converters Produce Garbage
- Which AI Bots Are Visiting Your Website? (And Which Aren’t)
- How to Read Your AI Crawler Analytics and Fix What’s Broken
- Getting Started with Getmd: Connect Your Website in 5 Minutes
- Getmd for WordPress, HubSpot, Shopify, and Webflow